Large Language Model Instructed Autonomous UAV Reinforcement Learning Framework
May 22, 2024
project lapse time: 2023-10-07 - 2024-05-22
Introduction
This research project explores a novel reinforcement learning (RL) framework for
autonomous unmanned aerial vehicles (UAVs) that leverages large language models (LLMs)
and human feedback to generate reward functions.
The goal is to address challenges in UAV navigation,
such as path planning in complex environments and target following,
by automating the design of reward functions with LLMs to improve the
efficiency and effectiveness of RL training.The experiments were conducted using Airsim,
Unreal Engine 4, and PyTorch
for deep learning implementations.
Project Details
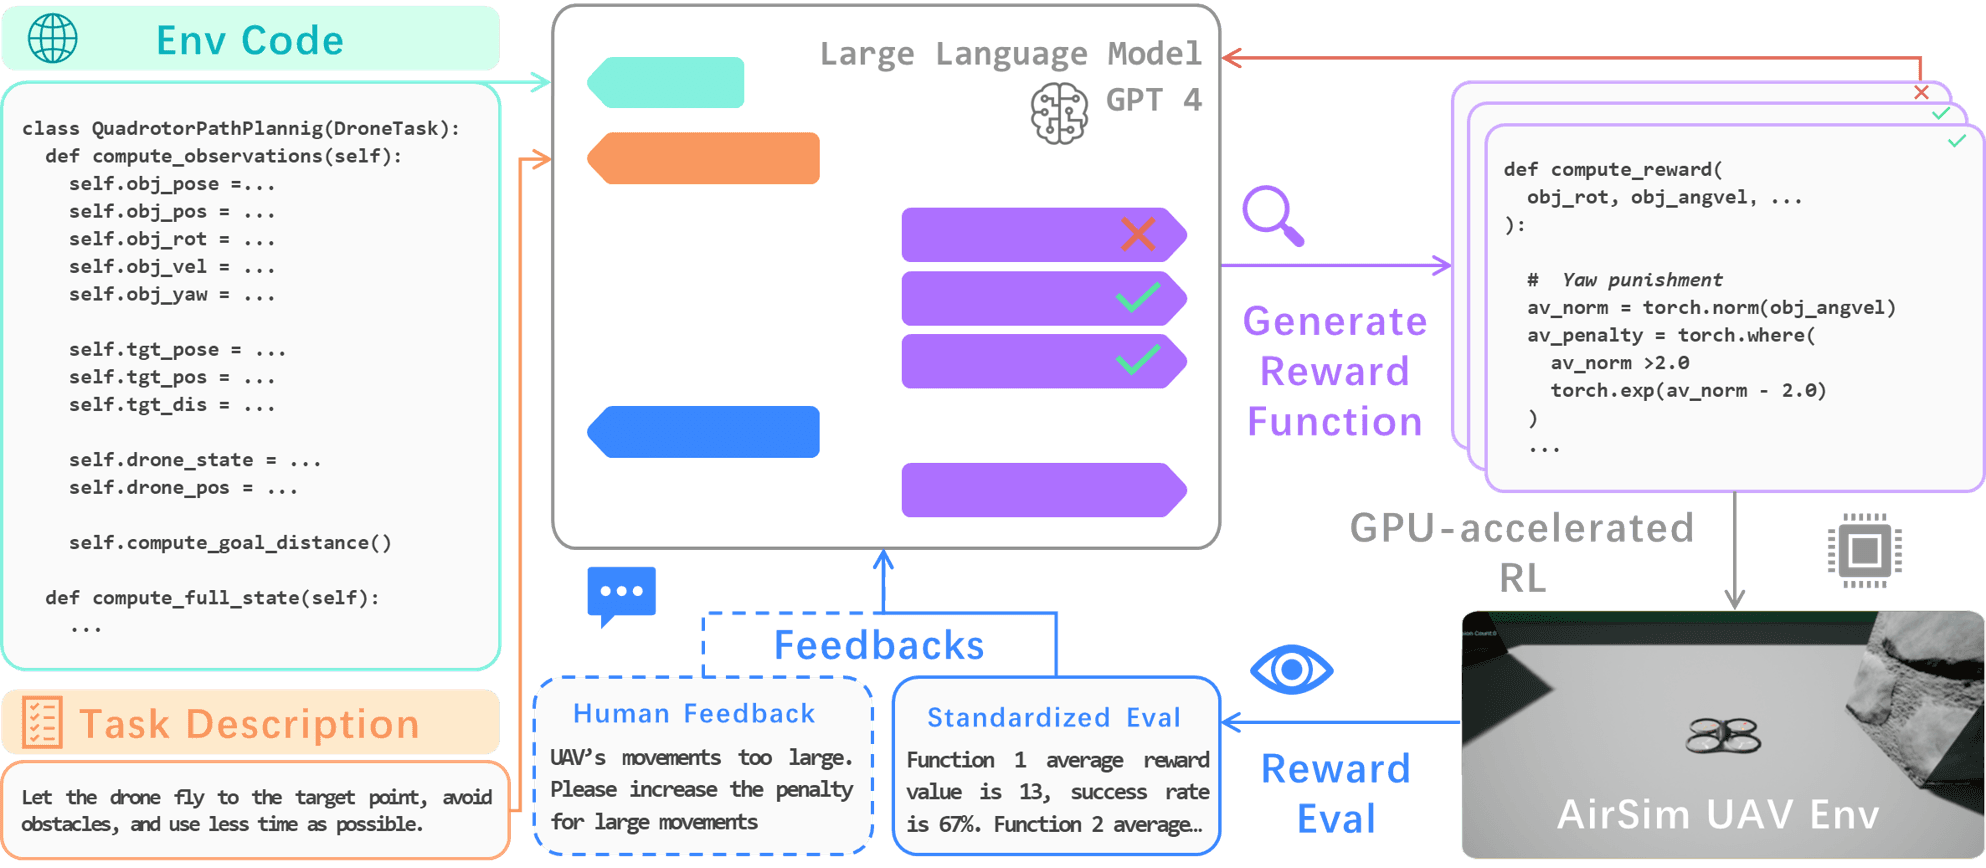
The project consists of four main modules: Reward Function Generation,
Reinforcement Learning, Simulation Environment, and Evaluation Iteration.
The Reward Function Generation module uses pretrained LLM APIs to automatically
generate reward functions from natural language task descriptions.
The Reinforcement Learning module optimizes UAV flight strategies using the PPO algorithm.
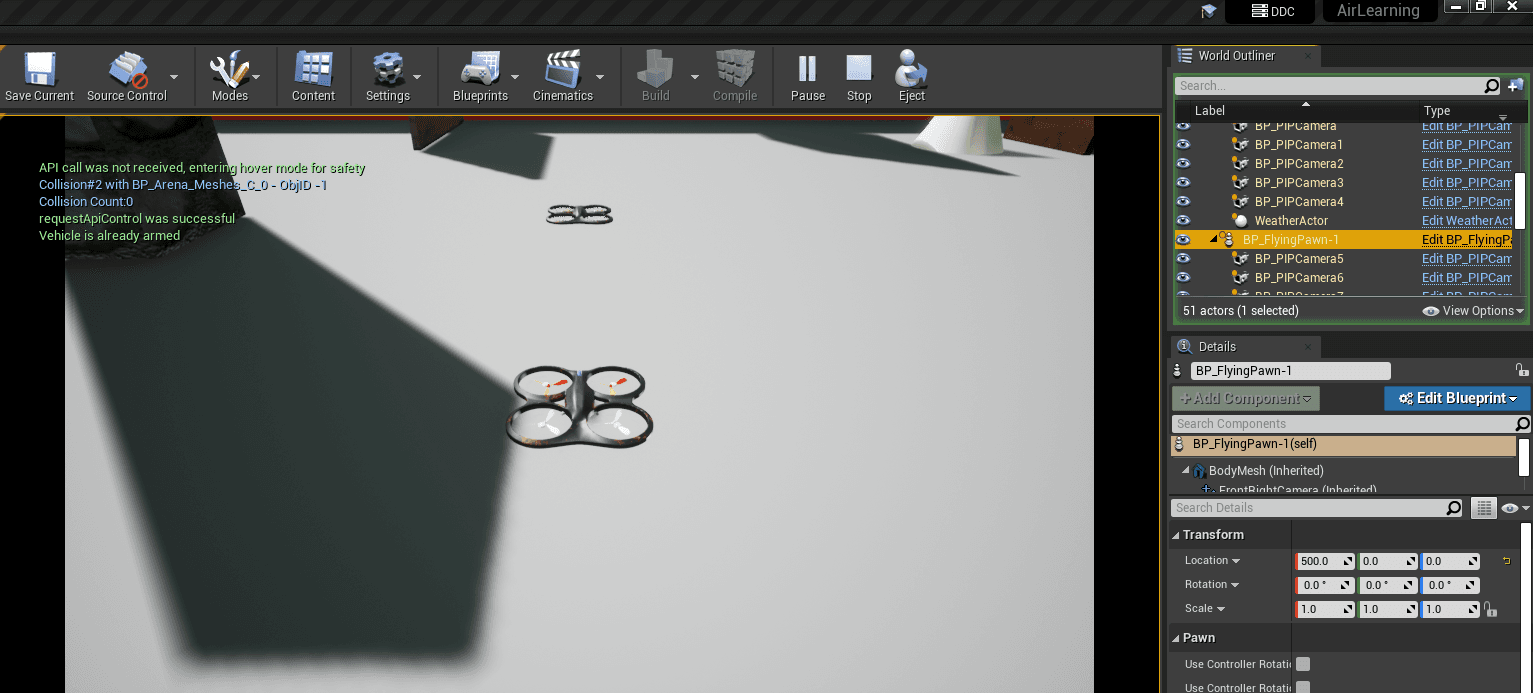
The Simulation Environment module employs Airsim for realistic 3D scene construction and UAV simulation.
The Evaluation Iteration module assesses UAV flight strategies and dynamically adjusts reward function
generation based on simulation data and human feedback.
The project evaluated the framework on two representative UAV autonomous flight tasks:
Path Planning and Perspective Following. The Path Planning task requires the
UAV to navigate from a starting point to an endpoint while avoiding obstacles.
The Perspective Following task demands the UAV to keep a dynamic target within its camera view.
Results
The framework demonstrated superior performance in generating high-quality reward functions,
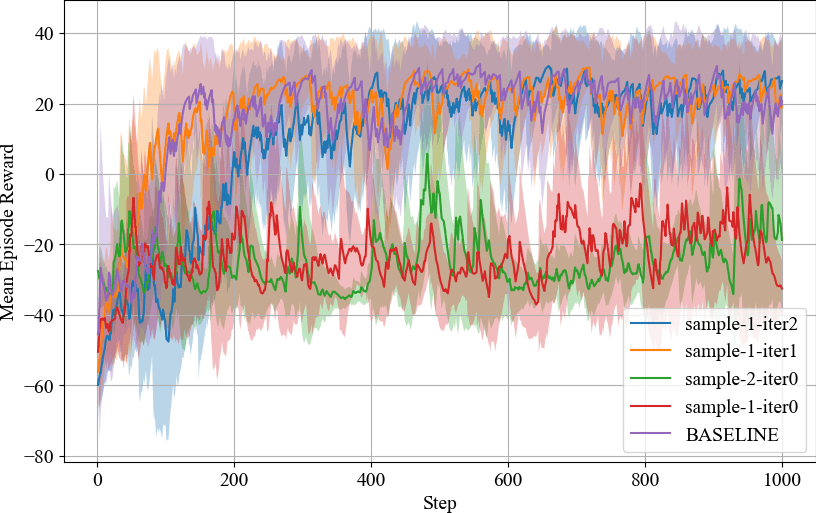
enabling UAVs to learn near-optimal flight strategies. In the Path Planning task,
the RL model trained using LLM-generated reward functions achieved a
7-11% higher success rate and 10-19% improvement in path quality compared to
expert-designed reward functions.
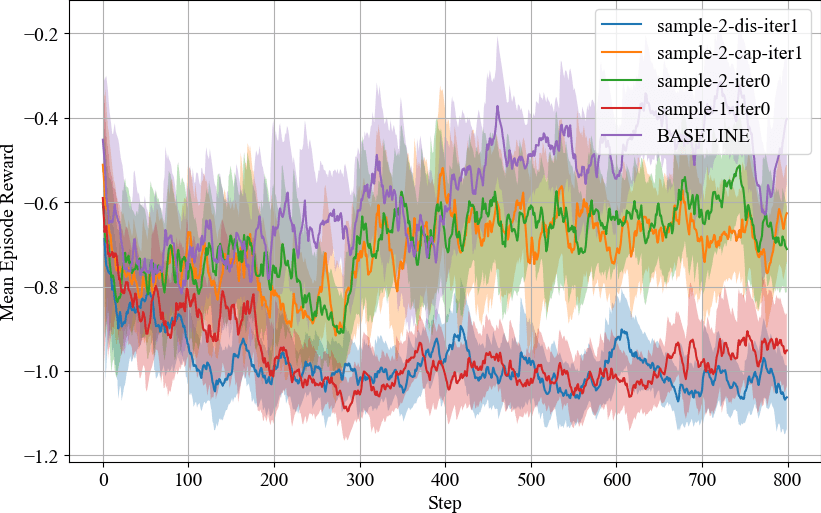
For the Perspective Following task, incorporating human feedback allowed for targeted
improvements in specific metrics such as target capture rate and frame distance error.
The framework showed an overall optimization effect when integrating human feedback
into the reward function generation process.
Conclusion
The research project demonstrates the effectiveness of using LLMs to generate reward functions
for RL-based autonomous UAV navigation. The proposed framework enhances the generalization and
adaptability of UAV flight strategies, outperforming traditional methods in complex scenarios.
This approach offers a new direction for intelligent upgrades in autonomous UAV flight,
achieving end-to-end automation from natural language task descriptions to optimized flight strategies.The work contributes to the field of autonomous systems and reinforcement learning,
potentially impacting applications such as search and rescue, environmental monitoring,
and logistics. Hopefully this research will inspire further exploration of LLM-assisted RL
frameworks for robotic systems.